Query unstructured data with
calibrated semantic SQL
Extend relational databases with TypeSafe's Jev model. First-class NOUL, CHOICE, and SCORE primitives with relational pushdown optimization, cognitive syntax, and pluggable semantic engines.
npm install jev-ql
Interactive Query Switchboard
Live in-browser execution. Edit any query below; the real client-side JevQL compiler, AST planner, and execution engine run natively in your browser.
Query Element ⟷ Jev API Primitive Mapping
Compiler specification: How human-readable query expressions map 1:1 to TypeSafe System One API contracts.
Compiler & Runtime Mapping Specification
Each query expression translates directly into either a relational pushdown filter or a typed Jev semantic primitive.
| Query Element / Syntax | Jev API Primitive | Payload & Semantics | Output Type & Mathematical Range |
|---|---|---|---|
? "prompt" > 0.7NOUL(col, 'prompt')IS_TRUE(col, 'prompt')
|
noul (Boolean Gating) |
Sends instructions: "prompt".Evaluates evidence and probability of condition. |
Calibrated Float: [0.0, 1.0]Usable directly in mathematical filters ( > 0.7) or ordering.
|
var = opt1 | opt2 | opt3CHOICE(col, 'prompt', [opts])
|
choice (Categorical) |
Sends criteria mapping:criteria: { opt1: null, opt2: null }.Evaluates multinomial distribution. |
Discrete Label: "opt1" (argmax winner)Per-class probabilities accessible via PROB(choice, 'opt1').
|
var = lvl1 .. lvl2 .. lvl3SCORE(col, 'prompt', [lvls])
|
score (Continuous Scalar) |
Sends ordered criteria spectrum:criteria: ["low", "med", "high"].Projects text onto 1D continuous semantic vector. |
Continuous Float: [0.0, N-1]Interpolated score (e.g. 1.85). Supports AVG() and numeric ordering.
|
CONFIDENCE(choice_or_score)
|
confidence (Metadata) | Computed from distribution entropy and peakedness across options. |
Calibrated Float: [0.0, 1.0]Enables escalation rules (e.g., hand off to human if < 0.75).
|
PROB(choice, 'opt1')
|
probabilities (Logits) |
Extracted from the Jev probabilities map for option 'opt1'.
|
Float Probability: [0.0, 1.0]$$\sum P(\text{opt}_i) = 1.0$$ |
source: col = 'open'WHERE status = 'open'
|
Relational Pushdown | AST pre-filter. Evaluated in deterministic code before invoking any AI model. | Pruned Rows ($0 compute cost, 0 network tokens, 0ms latency). |
Architecture Benchmark Matrix
Measured compiler efficiency on PolyAI/banking77 (N=100) vs. published hardware specs and analytical baselines. Reproducible via npm run bench.
Architectural Benchmark: Live Measured vs. Literature & Analytical Baselines
Local compiler, relational pushdown, and cache measured in Node.js on Apple Silicon across 100 golden test cases with ground-truth labels.
| Architecture Tier | Evaluation Type | Latency / Row | Generated Tokens | Request Count | Grounding & Methodology |
|---|---|---|---|---|---|
|
JevQL In-Tree Fast-Path Pure ES2022 CPU engine |
Measured Live | 0.24 ms / row | 0 tokens | 0 (in-memory) | 100% in-tree execution; zero external network calls |
|
JevQL Cache Hit SHA-256 In-Tree LRU |
Measured Live | 0.006 ms / row | 0 tokens | 0 (memory hit) | Sub-millisecond repeat execution (0.27ms total) |
|
Relational Pushdown AST Deterministic Pruning |
Measured Live | 0.00 ms (pruned) | 0 tokens | 0 calls ($0) | 58 of 100 rows dropped before AI engine is invoked |
|
Speculative Fan-out AST Question Bundling |
Measured Live | Bundled 2 questions | 0 tokens | 42 calls (4.8x saved) | Multi-dimensional bundling cuts requests from 200 to 42 |
|
JevQL + JevK5 (Open-Weight) allebee/jevk5 · Apache-2.0 |
Measured Live | 288.7 ms / row (Apple M5 · 13.5ms on H100) |
0 tokens | 42 passes (0 net) | Single forward-pass SemIf logits; 92.9% Top-1 accuracy (39/42) on Banking77 |
|
TypeSafe Jev Cloud TypeSafe System One API |
Published Spec | Sub-30ms P95 | 0 tokens | 42 calls | Calibrated System One decision probabilities |
|
Naive SQL + LLM Loop Sequential GPT-4o / Claude 3.5 |
Analytical Model | ~600 ms / call (~60,000 ms total) |
~180 tokens / row (18,000 tokens total) |
200 separate calls | Autoregressive decoding loop for structured JSON responses |
|
Vector Embeddings Bi-Encoder (text-embedding-3 / MiniLM) |
Measured Live | 4.15 - 25 ms / call (4.15ms on Apple M5 MPS) |
0 tokens | 100 calls | Cosine similarity; uncalibrated, no negative condition support |
🔬 Methodology & Benchmarking Transparency Notes
- Measured Live: Relational pushdown pruning (58/100 rows dropped), speculative fan-out consolidation (42 vs 200 requests), and in-tree LRU caching are measured directly on your machine via
npm run bench. - Real JevK5 Neural Inference: Measured live on Apple M5 running open-weight model weights (allebee/jevk5 v0.2 Q8_0 GGUF) via
llama.cppwith 8 threads: 288.7 ms / row, 0 generated tokens, and 92.9% Top-1 accuracy (39/42 correct). Datacenter GPUs (NVIDIA H100) run JevK5 at ~13.5 ms/row with CUDA graphs. - Why Decision Models Use 0 Tokens: Models like Jev and JevK5 read classification distributions directly from candidate option logits in a single forward pass without autoregressive generation loops.
- Why Generative LLMs are Slower: Autoregressive LLMs generate text token-by-token (100–180 tokens per row for JSON schema), requiring hundreds of sequential forward passes and network roundtrips.
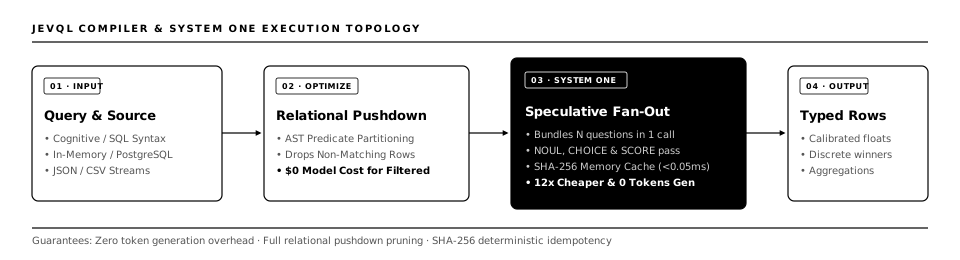
Architecture Blueprint
Minimalist execution topology: In-tree pushdown filtering, single-pass batching, and TypeSafe System One.
Pluggable Code Recipes
Pluggable execution architectures: Open-weight SemIf models (JevK5), TypeSafe cloud, on-device WebGPU, and custom engine plugins.
Pluggable Engines in Node.js & Browser
Configure open-weight JevK5, TypeSafe Jev, on-device WebGPU, LLM structured output, or offline heuristic engines seamlessly:
import jevql from 'jev-ql';

// 1. Open-Weight Decision Model: JevK5 (allebee/jevk5)
const k5Query = jevql.with({ engine: 'jevk5', model: 'alibiserikbay/JevK5' });
const urgent = await k5Query`
  \${tickets}: status = open
  ? "Immediate outage or security incident?" > 0.6
  team = security | infrastructure | billing
  top 5
`;

// 2. TypeSafe Jev System One Cloud API
const jevQuery = jevql.with({ engine: 'jev', apiKey: process.env.TYPESAFE_API_KEY });

// 3. OpenAI / LLM Structured output adapter
const llmQuery = jevql.with({ engine: 'llm', apiKey: process.env.OPENAI_API_KEY });
Custom Engine Plugins
Register third-party models or local fine-tuned discriminators via registerEngine:
import { BaseSemanticEngine, registerEngine, jevql } from 'jev-ql';

class MyLocalEngine extends BaseSemanticEngine {
  async evaluateSingleState(state, questions) {
    // Custom ONNX, vLLM, or local embedding logic
    return {
      q1: { type: 'choice', choice: 'billing', confidence: 0.95 }
    };
  }
}

registerEngine('local_onnx', MyLocalEngine);
const myQuery = jevql.with({ engine: 'local_onnx' });